ENEnglish
 LTLietuviškai
 DEDeutsch
 FRFrançais
 RUРусский
 ESEspañol
 PLPolski
 ITItaliano
 UKУкраїнська
 CSČeština
 PTPortuguês
 JA日本語
 LVLatviešu valoda
 ETEesti
 HUMagyar
 IDBahasa Indonesia
 TRTürkçe
 HIहिन्दी
 ELΕλληνικά
 ARالعربية
 THไทย
 VITiếng Việt
 RORomână
 MSBahasa Melayu
 BNবাংলা
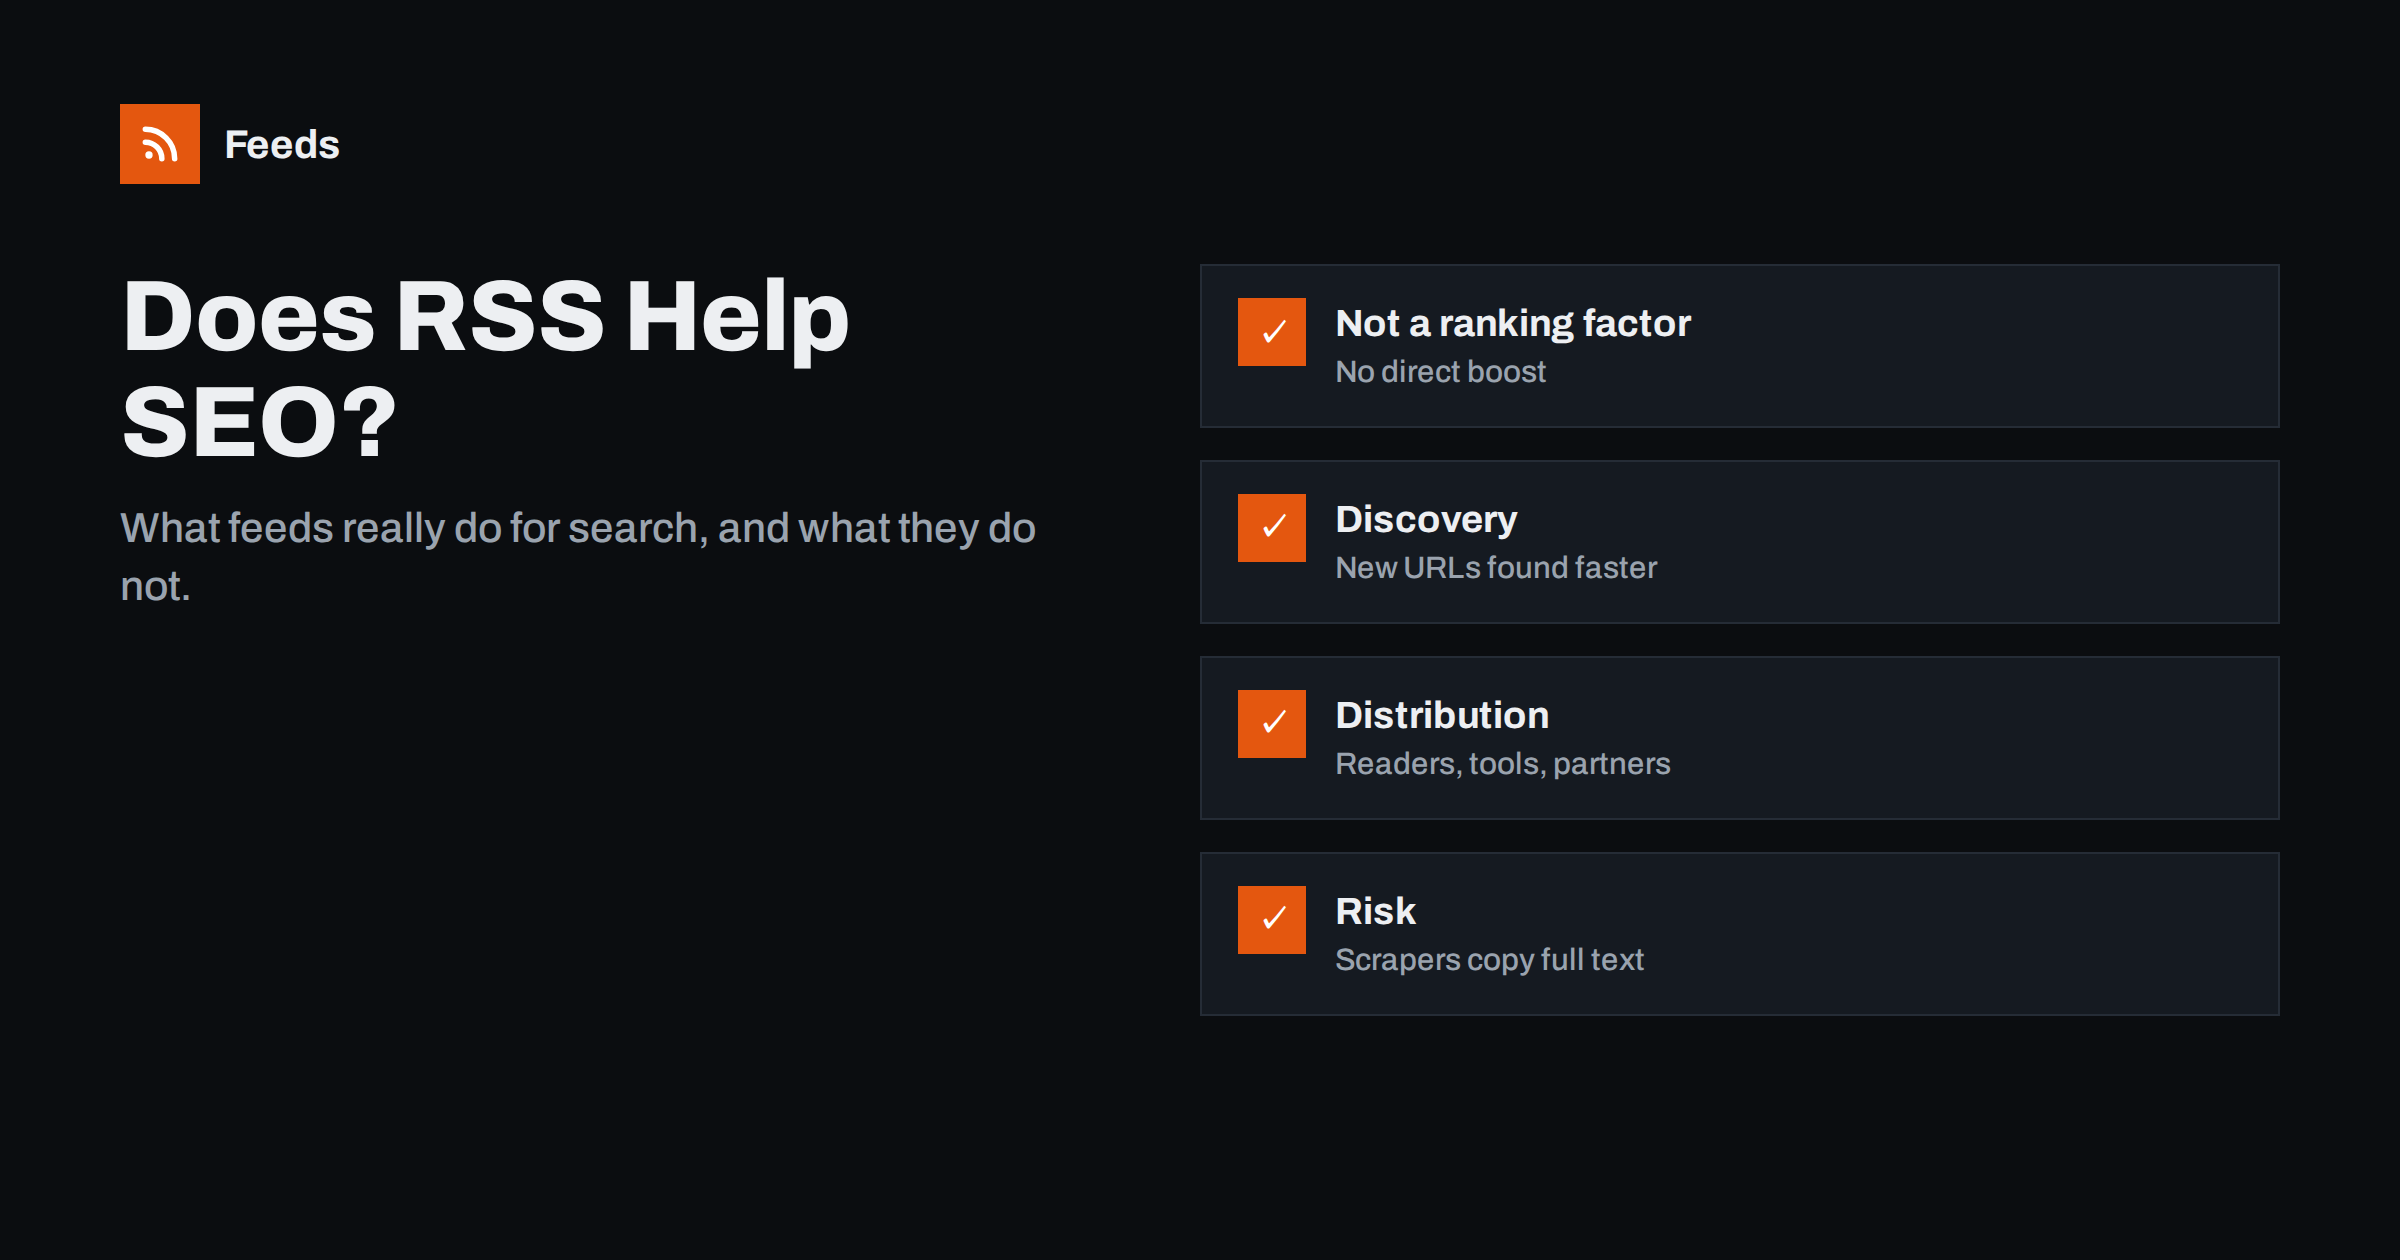
Short answer: An RSS feed does not improve rankings directly; search engines do not reward a site for having one. What a feed does is help search engines and other services discover new and updated pages quickly, and distribute your content to readers, newsletters, social tools and partners, which can bring visits and links. The main risk is scraping of full-text feeds, which you reduce with canonical tags and a link back to the original in every item.
SEO advice about RSS ranges from “submit your feed everywhere for backlinks” to “disable feeds because they cause duplicate content”. Both extremes are outdated. Feeds are neither a ranking trick nor a liability. They are a distribution channel with a few specific, useful effects on how your content is found. This guide separates what is well established from what is folklore, and gives a practical checklist for a search-friendly feed.
What search engines say about feeds
Google’s documentation for site owners mentions RSS and Atom feeds in the context of sitemaps: Google accepts RSS 2.0 and Atom 1.0 feeds as sitemaps, and recommends using both an XML sitemap and a feed, because the sitemap describes all URLs while the feed describes recent changes. You can read this in the Google Search Central sitemap guide. That is the core of the official story: feeds help crawlers find new and updated content.
Nowhere do search engines say that having a feed improves ranking, and there is no reason to expect it would. Rankings depend on the content, its relevance and quality, and signals about the page and site. A feed only changes how quickly and reliably a crawler learns that a page exists.
Benefit 1: faster discovery of new and updated pages
For a site that publishes frequently, a feed is a compact list of the latest URLs with their dates. Submitting it in Google Search Console alongside your XML sitemap gives the crawler a light file to check often. Practical points:
- Submit the feed as an additional sitemap in Search Console. It does not replace your XML sitemap.
- Make sure dates are accurate. Search engines use publication and update times as hints, and wrong dates reduce trust in the signal.
- Keep the feed reasonably short and focused on recent items; that is what it is for.
Feeds also help services other than search engines. Some news aggregators, podcast indexes and research tools discover new articles primarily through feeds, and they often check them more frequently than a general crawler checks a sitemap.
For a small site that publishes monthly, the effect is minor, because crawlers find new pages through internal links and the sitemap anyway. For news sites and large blogs, it helps more.
Feeds and XML sitemaps: how they work together
It is easy to confuse the two, because both are XML files that list URLs for machines. They do different jobs:
- The XML sitemap lists every page you want indexed, old and new, with optional last-modified dates. It can hold tens of thousands of URLs, split across several files. Crawlers download it occasionally to understand the whole site.
- The feed lists only the most recent items, usually ten to fifty, with titles, dates and summaries. It is small, changes every time you publish, and can be checked often at little cost.
Used together, they cover both needs: completeness from the sitemap and freshness from the feed. A few practical rules keep them consistent. Both should list the same canonical URLs, never a mix of HTTP and HTTPS or with and without trailing slashes. Dates in both should reflect real changes; updating the modified date of every page each night, as some plugins do, teaches crawlers to ignore the signal. And neither should include pages that are set to noindex, redirected or deleted.
If you run a large site, you can also publish several feeds, for example one per section, and submit the most important ones. For a typical business blog, the main feed alongside a standard sitemap is enough.
Benefit 2: distribution that can lead to visits and links
A feed puts your articles in front of people and systems you would not otherwise reach:
- Feed reader users, often professionals and journalists who may cite you.
- Newsletter tools that turn your feed into a digest.
- Social posting tools that share each new post.
- Industry aggregators and partner sites that list your headlines with links.
None of this is an SEO technique in itself, but visibility among the right audience is how content earns citations and links, which do matter for search. Links from aggregators are often marked nofollow or have little value; the real benefit is the people who read your work there.
Benefit 3: a clean data source for other tools
Many SEO and content tools read feeds: rank trackers that monitor new pages, content calendars, internal dashboards and AI assistants that summarise what is new on a site. A valid feed with good titles, dates and summaries makes your content easier to process correctly everywhere it travels.
The risk: scraping and duplicate content
Full-text feeds make it trivial for low-quality sites to republish your articles automatically. Search engines are generally good at identifying the original, especially when it was published first on an established site, but mistakes happen, particularly for new sites. Sensible precautions:
- Canonical tags on your own pages, pointing to themselves, so search engines know which URL is authoritative.
- A link back in each feed item, such as “The post [title] first appeared on [site]”, with an absolute URL. Scraped copies then link to you.
- Absolute internal links in content, so copies keep pointing to your pages.
- Consider summaries if scraping is a persistent problem for you, understanding that this also reduces the experience for genuine readers.
- Report serious cases through the search engine’s or host’s copyright processes.
Your own feed is not “duplicate content” in any harmful sense. Search engines understand what feeds are and do not treat feed URLs as competing pages. Many SEO plugins also send a noindex header for feeds, which keeps them out of search results entirely.
Myths worth retiring
- “Submitting your feed to hundreds of directories builds backlinks.” Feed directories were popular in the late 2000s; today most have vanished or offer no value, and mass submission can associate your site with spam.
- “Feeds cause duplicate content penalties.” There is no such penalty for having a feed. Scraping is a separate issue.
- “Disabling feeds improves crawl budget.” Feed URLs are tiny and cheap to crawl. For almost all sites, crawl budget is not a real constraint, and removing feeds removes useful discovery and distribution.
- “A feed is a ranking factor.” It is not.
A checklist for a search-friendly feed
| Check | Why it helps |
|---|---|
| Feed is valid RSS or Atom | Crawlers and tools parse it reliably |
| Accurate publication and update dates with time zones | Trustworthy freshness hints |
| Absolute item links that match canonical URLs | No confusion over which URL is the original |
| Link back to the original in every item | Scraped copies point to you |
| Good titles and excerpts | Better presentation in readers, emails and social posts |
| Featured images in the feed | More attractive wherever the feed is displayed |
| Feed submitted in Search Console with the XML sitemap | Faster discovery of new URLs |
| Autodiscovery tag on every page | Tools and readers find the feed automatically |
Feeds of other sites as an SEO research tool
Feeds are also useful on the research side: following competitors’ blogs, industry publications and news in one reader shows you which topics others cover, how often, and how they frame them. When a site you want to follow has no feed, you can still watch it. Our tool, Feeds, creates an RSS feed from a page that lists articles, uses an existing feed where one exists, and can merge several sources and keep only items that mention your keywords. The result is a single link for your reader or content calendar. See the plans.
Related reading
- Full Text or Summary? Choosing What Your RSS Feed Shows
- How to Track Competitor Blogs and News with RSS Feeds
- How to Validate an RSS Feed and Fix the Most Common Errors
The bottom line
An RSS feed will not lift your rankings on its own, but it helps search engines discover new pages faster, spreads your content to readers and tools that can bring visits and citations, and gives everyone a clean list of what is new. Keep it valid, accurate and linked back to the originals, submit it alongside your sitemap, and ignore the old myths about feed directories and penalties.
الأسئلة الشائعة
Is an RSS feed a ranking factor?
No. Search engines do not rank pages higher because a site has a feed. A feed helps crawlers discover new and updated pages, which can make indexing faster, but rankings depend on the pages themselves.
Should I submit my RSS feed to Google Search Console?
It is a good idea for sites that publish often. Google accepts RSS and Atom feeds as sitemaps and recommends using a feed together with an XML sitemap, not instead of one.
Can a full-text feed cause duplicate content problems?
Your own feed does not. The risk is other sites scraping and republishing your articles. Canonical tags and a link back to the original in every feed item reduce the impact.
Should I disable RSS feeds for SEO reasons?
For almost all sites, no. Feeds are cheap to crawl and useful for discovery and distribution. Disabling them removes a free channel without any real SEO gain.
Are RSS feed directories worth submitting to?
Generally not. Most feed directories are gone or provide no meaningful value. Focus on making your feed discoverable through autodiscovery tags and on relevant, real aggregators in your industry.