 ENEnglish
 LTLietuviškai
 DEDeutsch
 FRFrançais
 RUРусский
 ESEspañol
 PLPolski
 ITItaliano
 UKУкраїнська
 CSČeština
 PTPortuguês
 JA日本語
 LVLatviešu valoda
 ETEesti
 HUMagyar
 IDBahasa Indonesia
 TRTürkçe
 HIहिन्दी
 ELΕλληνικά
 ARالعربية
 THไทย
 VITiếng Việt
 RORomână
 MSBahasa Melayu
 BNবাংলা
#Web Scraping
Web scraping is the automated extraction of data from web pages, usually with custom code that targets specific elements of a page. It is powerful but fragile, because small layout changes can break a scraper, and it needs care around load and site terms. Many monitoring needs can be met with lighter methods, such as existing feeds, structured data or page-to-feed tools. Understanding the difference helps teams choose the least brittle option for each job. Articles under this tag compare scraping with feeds and explain when each approach makes sense.
 19 nov. 2026 · 8 min de citit
RSS Feed Creator vs Writing Your Own Page Scraper
Is it worth writing a script to turn a web page into a feed? See what a scraper needs beyond the first version and…
 18 nov. 2026 · 8 min de citit
Which Web Address to Paste: Home Page, Section or Search?
Which address works best in RSS Feed Creator: home page, section page, filtered search or feed address, how addresses are cleaned, and multilingual sites.
 13 nov. 2026 · 7 min de citit
How RSS Feed Creator Finds Items on Pages Without RSS
How RSS Feed Creator turns a plain web page into a feed: it looks for an existing feed, reads article data, then spots repeated…
 20 aug. 2026 · 8 min de citit
Is It Legal to Create RSS Feeds from Other Websites?
Making a feed from someone else's site is common, but what you do with it matters. A practical look at reading, linking, republishing and…
 18 aug. 2026 · 8 min de citit
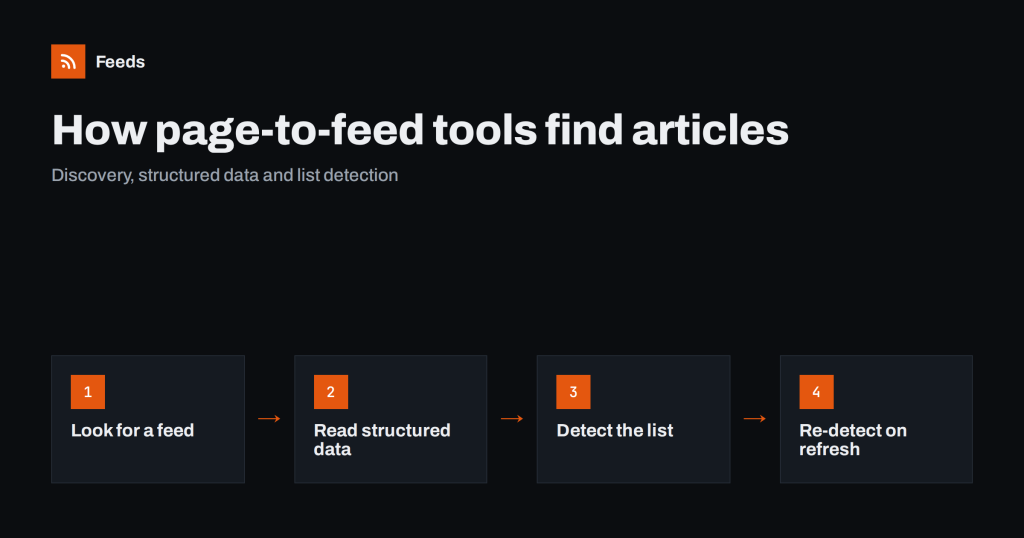
How Page-to-Feed Tools Find the Articles on a Web Page
What happens when you paste a page address into a page-to-feed tool: feed discovery, structured data, list detection and how refreshes keep a feed…
 3 aug. 2026 · 8 min de citit
RSS vs Web Scraping: Which Should You Use to Track Sites?
RSS and web scraping both pull content from websites, but they differ in effort, fragility and etiquette. Here is how to choose the right…