ENEnglish
 LTLietuviškai
 DEDeutsch
 FRFrançais
 RUРусский
 ESEspañol
 PLPolski
 ITItaliano
 UKУкраїнська
 CSČeština
 PTPortuguês
 JA日本語
 LVLatviešu valoda
 ETEesti
 HUMagyar
 IDBahasa Indonesia
 TRTürkçe
 HIहिन्दी
 ELΕλληνικά
 ARالعربية
 THไทย
 VITiếng Việt
 RORomână
 MSBahasa Melayu
 BNবাংলা
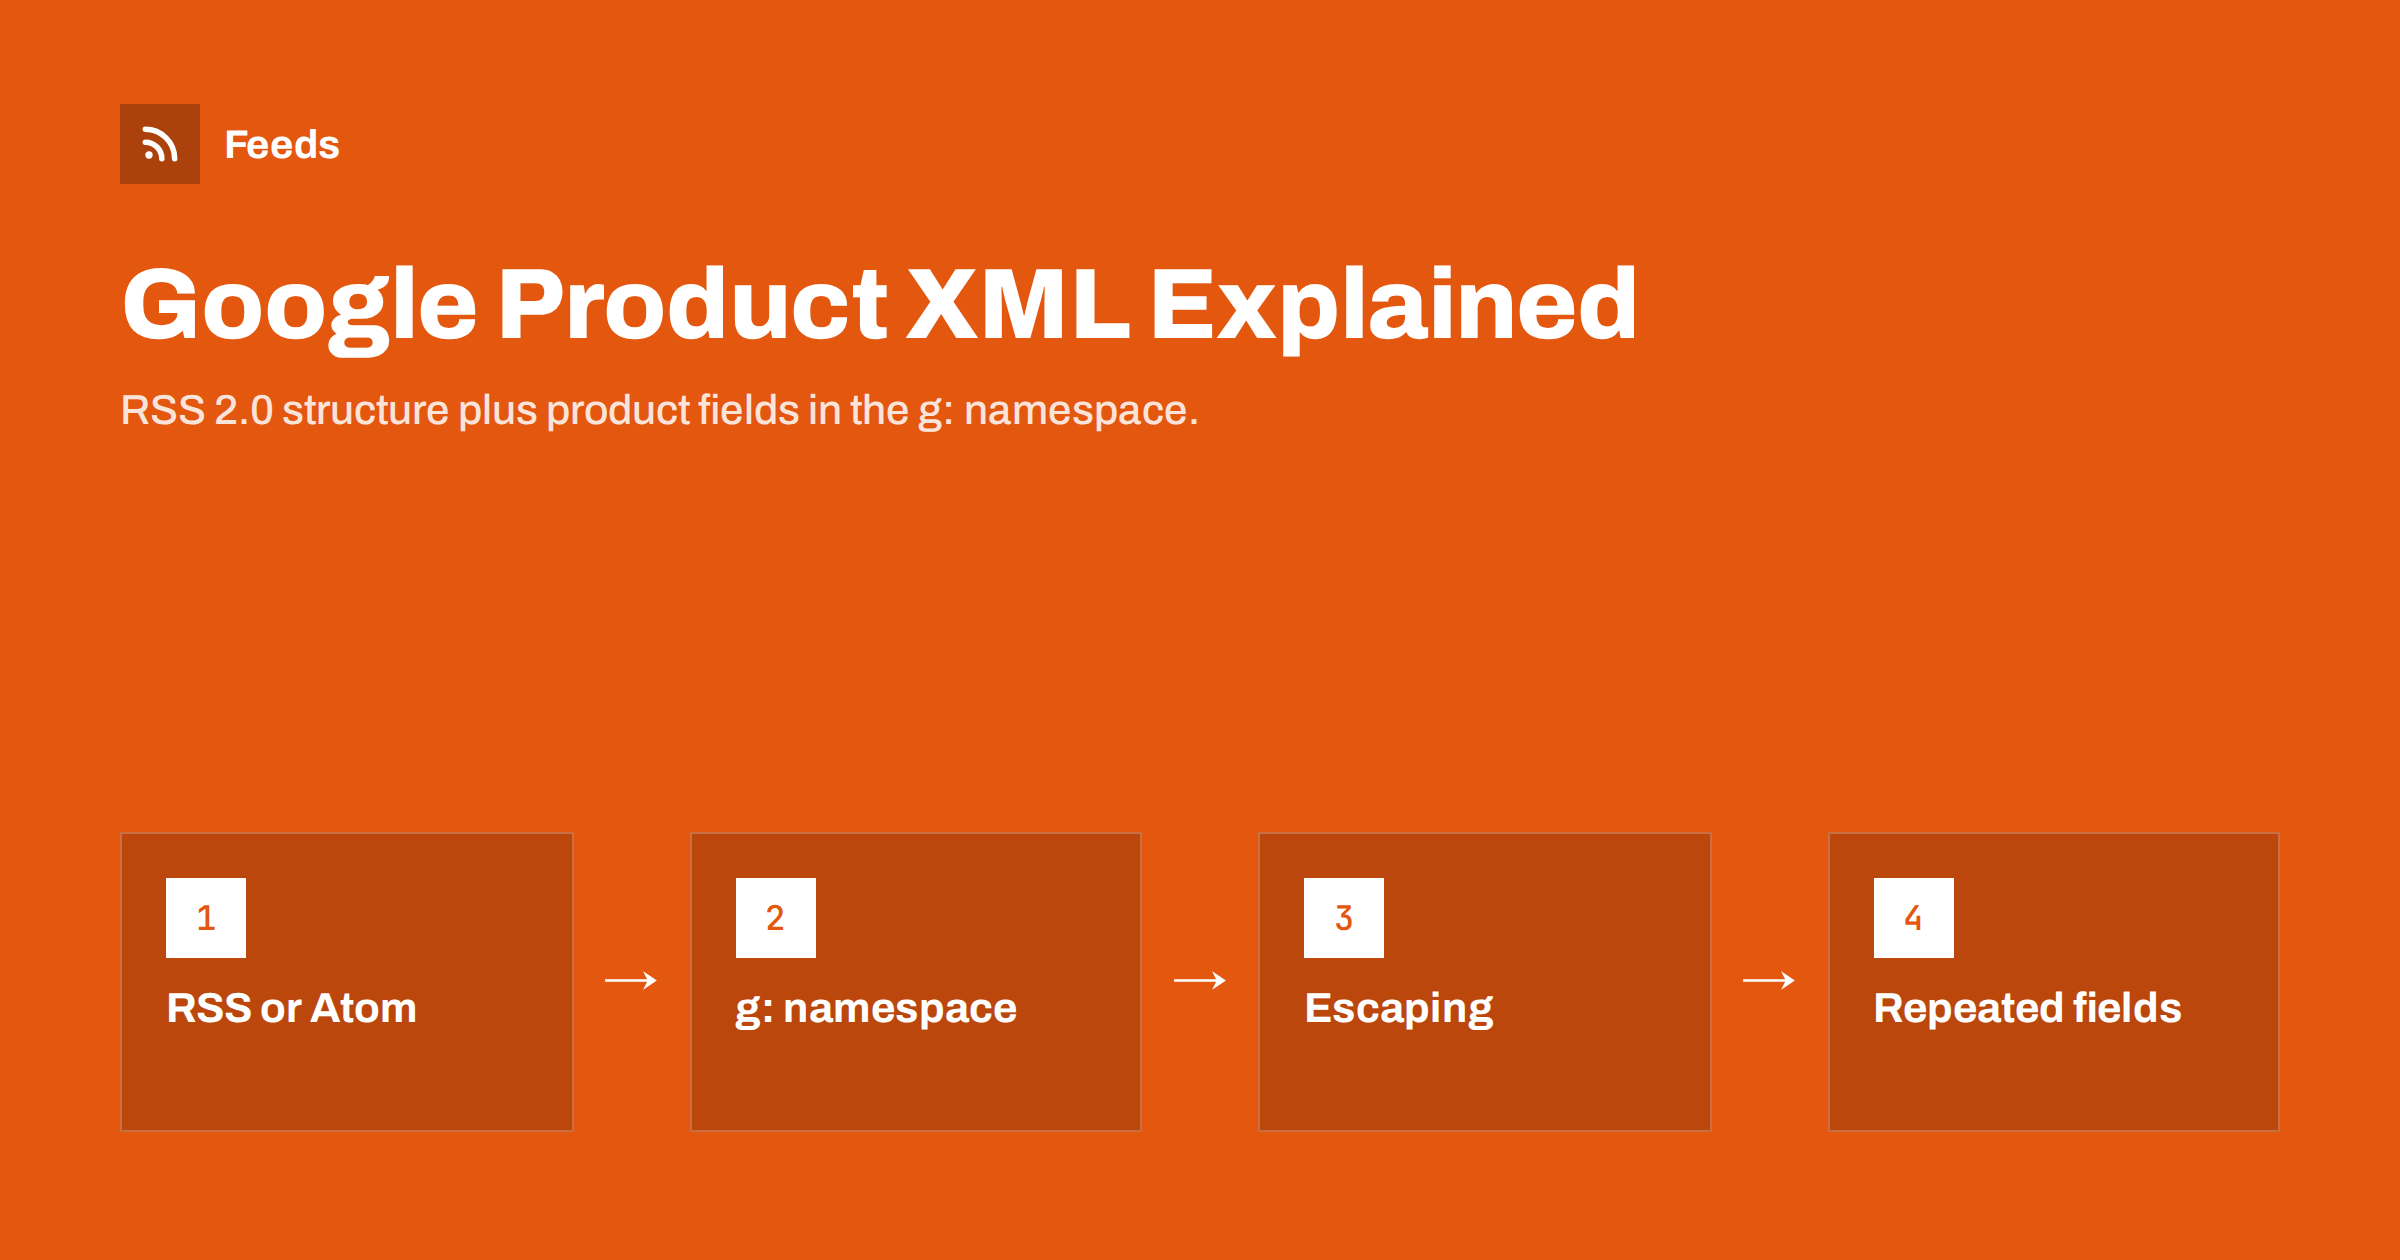
Short answer: Google’s product XML format is an RSS 2.0 (or Atom 1.0) feed in which each product is an item element, and product attributes are added as elements in Google’s namespace, written with a g: prefix, such as g:id, g:price and g:availability. The file must be well-formed XML in UTF-8, with special characters escaped. Repeated attributes, such as additional images, are simply repeated elements. Meta and many other platforms read the same format.
Why product feeds borrowed RSS
RSS was designed to publish a list of items, such as blog posts, in a standard way that any reader can process. A product catalog is also a list of items. Instead of inventing a completely new format, Google extended RSS: the familiar channel and item structure stays, and product-specific fields are added through an XML namespace.
That choice has practical benefits. Many tools already know how to generate and parse RSS. The structure is easy to understand. And because namespaces are a standard XML feature, the product fields can coexist with regular RSS fields without conflict. Atom 1.0, another feed standard, can be extended in the same way, and Google accepts both.
It also explains why a normal blog RSS feed is not a product feed: it has the structure, but not the product fields that shopping platforms require.
For store owners, the practical takeaway is simple: you rarely need to write this XML by hand. But understanding its structure makes it much easier to read a feed file, spot a problem and explain it to whoever maintains the generator. Ten minutes spent opening your own feed in a browser is often the fastest way to understand what platforms actually receive.
The overall structure
An RSS-based product feed has three layers:
- The rss root element, with version 2.0 and a namespace declaration that binds the g prefix to Google’s base namespace URL.
- A channel element with a title, link to the store and a short description of the feed.
- One item element per product or variant, containing the product attributes.
The namespace declaration is essential. Without it, g:price is just an unknown element name and the file is not valid in the way platforms expect. Feed generators add it automatically; hand-built files often forget it.
In Atom, the equivalent is a feed root element with entry elements instead of items, and the same g namespace for product attributes. Choose one format and stay with it; there is no advantage in switching.
The channel-level elements are informational. Platforms do not use the channel title for anything important, but a clear title such as the store name and feed purpose helps humans who open the file later.
Inside an item
Each item contains the attributes for one product, most of them with the g: prefix:
- g:id: the unique product identifier.
- g:title (or the plain RSS title element): the product title.
- g:description (or the plain description element): plain-text description.
- g:link (or the plain link element): the landing page URL.
- g:image_link: the main image URL.
- g:availability: in_stock, out_of_stock, preorder or backorder.
- g:price: a number followed by an ISO currency code, such as 49.90 EUR.
- g:brand, g:gtin, g:mpn, g:condition and other attributes as needed.
Title, link and description can use the standard RSS elements or the g: versions. Using one convention consistently is more important than which one you choose.
Item order does not matter to platforms, and neither does the order of elements within an item. What matters is that each item is complete and each value is valid. Sorting items by ID can still be useful for people comparing two versions of a feed, because differences are easier to spot.
Attribute values are case-sensitive in some places. Availability values like in_stock should be written exactly as documented, and currency codes should use the standard three uppercase letters. Consistent casing avoids surprises when platforms tighten validation.
Repeated and nested attributes
XML handles repeated and structured data naturally, which is one of its advantages over CSV:
- Additional images: repeat g:additional_image_link once per image.
- Shipping: g:shipping contains sub-elements such as g:country, g:service and g:price, and can be repeated per country or service.
- Product details: g:product_detail contains g:section_name, g:attribute_name and g:attribute_value, repeated per specification.
- Product highlights: repeat g:product_highlight per bullet point.
In a CSV file, the same data has to be packed into one field with separators and colons, which is harder to read and easier to break.
Escaping and encoding
XML has a few characters with special meaning. Inside text, they must be escaped or the file becomes invalid:
| Character | Escape as | Where it appears |
|---|---|---|
| & | & | Brand names, titles, URLs with parameters |
| < | < | Descriptions with leftover HTML |
| > | > | Category paths such as Home > Kitchen |
| “ | " (in attributes) | Sizes in inches, quotes in titles |
Alternatively, text can be wrapped in CDATA sections, which tell the parser to treat the content as plain text. Unescaped ampersands in URLs are one of the most common reasons a hand-built XML feed fails to parse. The file should be saved as UTF-8, and the XML declaration at the top should say so.
If you generate XML with a proper library rather than by concatenating strings, escaping and encoding are handled automatically. Most encoding and escaping bugs come from templates that paste raw text into XML without passing it through the library.
Validating an XML feed
- Well-formedness: open the file in a browser or XML tool; any syntax error is reported with a line number.
- Namespace: check that the root element declares the g namespace.
- Item count: count item elements and compare with the number of products you expect.
- Sample values: inspect a few items for correct prices, currencies and availability values.
- Platform test: submit the file as a test source and read the processing report before making it primary.
Merchant Center reports parsing problems and attribute errors after processing. A drop in the number of items processed compared with the number in the file is a sign that some items could not be read.
Common XML feed mistakes
Most broken XML feeds fail for a small set of reasons. Knowing them makes troubleshooting much faster:
- Missing namespace declaration. The g: elements appear, but the root element never binds the prefix, so parsers reject or ignore them.
- Unescaped characters. An ampersand in “Black & Decker” or in a URL query string breaks the whole file if written raw.
- HTML inside descriptions. Tags such as paragraph or line break elements confuse the structure unless wrapped in CDATA, and they should not be in the feed anyway.
- Invalid control characters. Invisible characters pasted from word processors or old databases are not allowed in XML and can stop parsing at that item.
- Byte order and encoding mismatches. A file declared as UTF-8 but saved in another encoding produces garbled text or errors.
- Truncated files. A generation process that times out halfway leaves a file without closing tags, which platforms cannot read.
The last point is worth emphasizing. A truncated file often looks fine at the top, and the problem is only visible at the end. Checking that the file ends with the closing rss or feed element is a quick sanity test after every generation.
XML for Meta and other platforms
Meta’s catalog accepts XML feeds in RSS and Atom format and recognizes Google’s attribute names, so a correctly built Google product XML file usually works there without changes. Many comparison sites and marketing tools accept the same format. That portability is a strong reason to use XML as the main format for a store’s product data, even if some destinations also accept CSV.
Some marketplaces have their own XML schemas with different element names and required fields. For those, the data is the same but the structure differs, and a separate feed or a conversion step is needed.
If you maintain feeds for several destinations, keep the Google format as the master and derive others from it. That way the core data is validated once, and destination-specific differences stay small and visible.
How Feeds helps
Feeds generates Google product XML automatically from WooCommerce, Shopify or a CSV link, with the namespace, escaping and required elements handled for you: id, title, link, image, price, availability and brand. Merchant Center and Meta can both fetch the file, which refreshes automatically. Rules skip out-of-stock products, rewrite titles and adjust prices. See the pricing page for plans.
Related reading
- XML vs CSV vs Google Sheets: Which Product Feed Format?
- RSS vs Atom: Which Feed Format Should Your Site Publish?
- Google Product Feed Attributes: Required and Recommended
The bottom line
Google’s product XML is RSS 2.0 or Atom with product attributes in the g namespace: a root element with the namespace declaration, a channel, and one item per product. Escape special characters, save in UTF-8, use repeated elements for multi-value attributes, and validate before switching sources. The same file typically serves Meta too.
SSS
Is a Google product feed an RSS feed?
Structurally yes. It uses RSS 2.0 or Atom with extra product fields in Google’s namespace. A regular blog RSS feed lacks those fields and is not a product feed.
What does the g: prefix mean?
It marks elements from Google’s product namespace, declared at the top of the file. Attributes like g:price and g:availability use it.
Why does my XML feed fail to parse?
The most common cause is an unescaped ampersand, often in URLs or brand names. Other causes are leftover HTML and wrong encoding.
Can I include several images in XML?
Yes. Repeat g:additional_image_link once for each extra image, up to the platform’s limit.
Does Meta accept Google’s XML format?
Yes. Meta catalogs accept RSS and Atom XML feeds and recognize Google’s attribute names.